Does a Full-Duplex Spoken Dialogue Model Use the Face It Sees?
Measuring own- and partner-face turn-taking cues by input intervention全二重音声対話モデルは,見ている顔を使っているか?
自分の顔と相手の顔のターンテイキング手がかりを,入力への介入で測る
Under review査読中
Paper & code: coming soon論文・コード: 準備中
A full-duplex spoken dialogue model that takes the user's face and audio as input and produces its own face and audio. We ask a simple question: does the model actually use the face it receives to decide when to take the turn?ユーザの顔と音声を入力として受け取り,自分の顔と音声を出力する全二重音声対話モデル.問いは単純で,モデルは受け取った顔を,ターンを取るタイミングの判断に実際に使っているのか,である.
User (recorded): “… but food should be fine. You should be able to eat whatever you can stomach while you’re not feeling well.” Model (generated): “I hate that. I got in trouble. And I like got up in the middle of the night. And I started getting a different diet. Like, I was like, oh, my body’s like …”
Input on the left, output on the right. Left: the user in a held-out recording. The model does not see the pixels; it receives the user's audio and 61 facial coefficients extracted from this video. Right: the model's own audio and face. After the red dashed line the model generates its speech, its text and its facial coefficients (fed back as its next input); before the line they are the recorded context. To make the generated coefficients visible, we animate a synthetic portrait (not a real person) with them: head rotation, jaw and mouth, blinks, smile, brows and gaze. Dots on the faces mark six of the 61 coefficients (chin = jawOpen, mouth corners = mouthSmile, upper eyelids = eyeBlink, inner brows = browInnerUp, nose = head rotation); their size is the coefficient value, and the panel at the bottom plots the same six over time: on the left what the model receives, on the right what it generates. 🔊 The clip has sound.左が入力,右が出力.左: 学習に使っていない録画の中のユーザ.モデルは画素を見ておらず,受け取るのはユーザの音声と,この映像から取り出した 61 個の顔係数である.右: モデル自身の音声と顔.赤い点線より後ろでは,モデルが音声・テキスト・顔係数を生成している(顔係数は次の入力として戻される).点線より前は文脈として与えた録音である.生成された係数を目で見えるようにするため,その係数で合成の顔写真(実在しない人物)を動かしている(頭の回転,顎と口,まばたき,笑み,眉,視線).🔊 音が出ます.
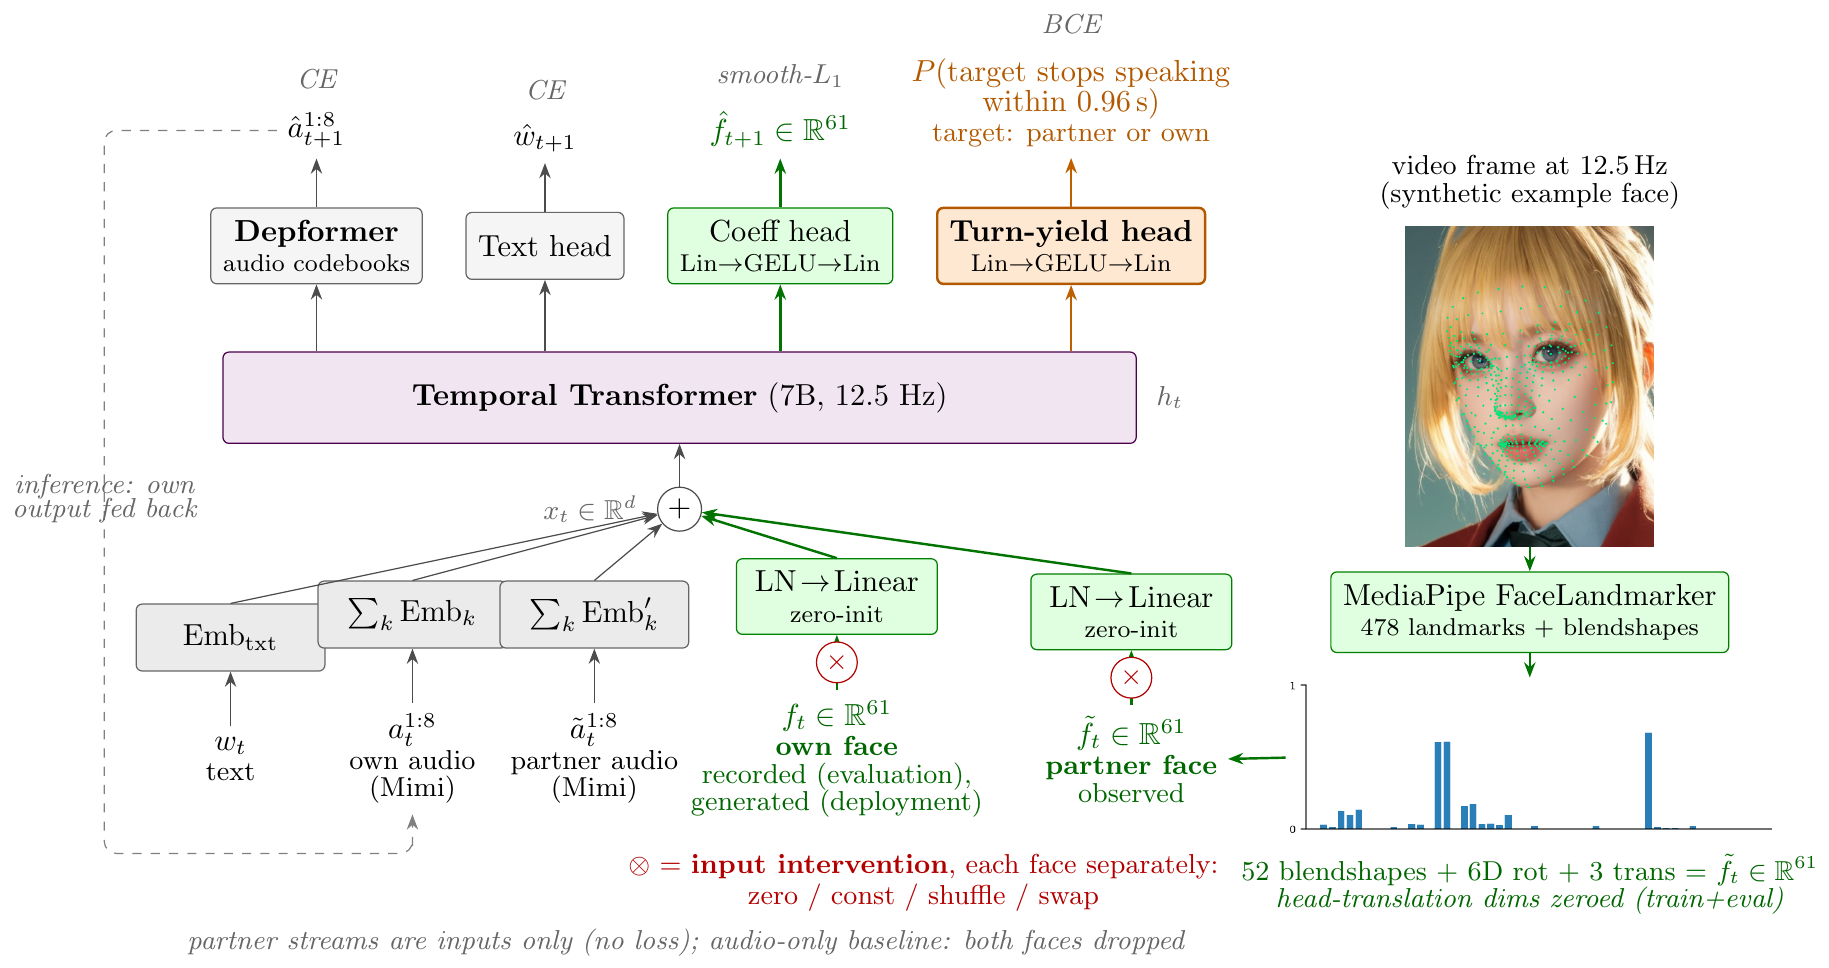
TL;DR — We add two streams of facial coefficients, the model's own face and the partner's face, to a full-duplex audio language model, and replace each stream separately on held-out spontaneous conversations. The model uses the partner's face: removing it lowers the AUC for turn shifts by 0.006 to 0.010 in all three training runs, the loss doubles at 0 dB SNR, and without the partner's face the model speaks into the partner's pauses 9 points more often. It relies on head and mouth movement aligned with the audio. Replacing each face separately also shows that the model's gain over a matched audio-only model comes from its own recorded face, a stream that only exists offline: a model trained with the partner's face alone depends on it (0.013) yet matches the audio-only model. Dependence and gain must be measured per face, with speech-derived turn ends.要約 — 全二重の音声言語モデルに,モデル自身の顔と相手の顔の 2 本の顔係数ストリームを加え,学習に使っていない自発会話の上で,それぞれを別々に差し替えた.モデルは相手の顔を使っている: 相手の顔を消すと,話者交替の AUC が 3 回の学習すべてで 0.006〜0.010 下がり,0 dB の雑音下では 2 倍になり,相手の顔が無いと相手の間に割り込む率が 9 ポイント増える.効いているのは音声と同期した頭と口の動き.顔を 1 本ずつ差し替えると,顔なしの対照モデルに対する上積みは録画された自分の顔(実運用には無い入力)から来ていることが分かる: 相手の顔だけで学習したモデルは相手の顔を使う(0.013)が,音声のみモデルと同水準である.「使っているか」と「役に立っているか」は顔ごとに,発話由来のターン終了で測る必要がある.
How we measure it測り方
Listening tests cannot tell whether a model uses the face: a model can sound natural with or without it. We therefore intervene on the input. A small head predicts whether the partner stops talking within about one second, and we watch how its predictions change when a facial stream is replaced by zeros, by its mean, by a time-shuffled copy, or by the face from another conversation.聴取テストでは,モデルが顔を使っているかどうかは分からない(顔を使っても使わなくても,同じくらい自然に聞こえうる).そこで入力に介入する.小さなヘッドが「相手が約 1 秒以内に話し終わるか」を予測し,顔のストリームをゼロ・平均・時間シャッフル・別の会話の顔に差し替えたときに,その予測がどう変わるかを見る.
Model and measurement. Each facial stream is replaced separately at test time. The example face is synthetic.モデルと測定.テスト時に顔のストリームを 1 本ずつ差し替える.例の顔は合成画像.
1
Replace each face separately顔を 1 本ずつ差し替える
The partner's face is observed at deployment; the model's own face is recorded in evaluation but generated at deployment.相手の顔は実運用でも観測される.自分の顔は,評価では録画だが実運用では自己生成になる.
2
Define turn ends from speechターン終了は発話から定義する
Labels come from word timings, never from the video, so the label is independent of the input under test.ラベルは単語の時刻から作り,映像からは作らない.調べたい入力とラベルを独立にするため.
3
Train a matched audio-only model条件を揃えた音声のみモデルを学習する
A drop under intervention shows dependence; the comparison with a model trained without faces shows gain.介入で下がることは依存を示す.顔なしで学習したモデルとの比較が,上積みを示す.
Results結果
Held-out Seamless Interaction conversations (156 conversations, 130k scored frames). Positives are turn shifts, where the other speaker takes over. The score and the decision rule were fixed before any model was evaluated.Seamless Interaction の未使用会話(156 会話,13 万フレーム).陽性は話者交替(もう一方の話者が話し始める場合).指標と判定基準は,どのモデルも評価する前に固定した.
Model (seed)モデル(seed)
AUC
Δ both faces removedΔ 両方の顔を消す
Δ partner's face removedΔ 相手の顔を消す
Δ own face removedΔ 自分の顔を消す
audio-only (42)音声のみ (42)
.692
–
–
–
audio-only (43)音声のみ (43)
.705
–
–
–
audio-only (44)音声のみ (44)
.701
–
–
–
face (42)顔あり (42)
.714
+.017
+.006 [.004, .009]
+.011
face (43)顔あり (43)
.713
+.020
+.010 [.008, .013]
+.012
face (44)顔あり (44)
.710
+.016
+.006 [.003, .008]
+.011
partner-only (42) — own face zeroed in training and evaluation相手の顔のみ (42) — 学習・評価とも自分の顔をゼロ
.692
–
+.013 [.010, .016]
–
Brackets: 95% confidence intervals from a bootstrap that resamples whole conversations. With both faces, the face model is better than the audio-only model in all nine pairings of a face run with an audio-only run (+0.005 to +0.022; eight of the nine intervals exclude zero). With the own face zeroed it is level with the audio-only model (seven of nine intervals include zero): the gain comes from the recorded own face. The partner-only model, the deployment configuration, depends on the partner's face by 0.013 and is level with the audio-only model (+0.000 [−.006, +.006]).[ ] は会話単位で再標本化した bootstrap の 95% 信頼区間.両方の顔ありでは,顔ありモデルは音声のみモデルとの 9 通りの組み合わせすべてで上回る(+0.005〜+0.022,うち 8 通りで区間が 0 を含まない).自分の顔をゼロにすると音声のみモデルと同水準になる(9 通り中 7 通りで区間が 0 を含む): 上積みは録画された自分の顔から来ている.相手の顔のみモデル(実運用の構成)は相手の顔を使う(0.013)が,音声のみモデルと同水準(+0.000 [−.006, +.006]).
Which facial cues matter?どの手がかりが効いているか
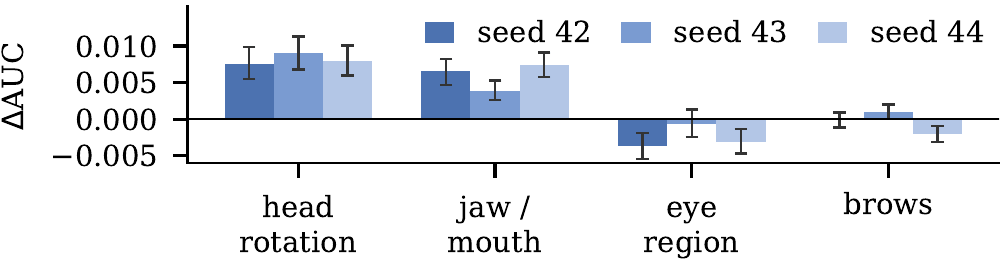
Loss in AUC on the primary score when one group of the partner's facial coefficients is zeroed (own face kept), for three training runs. Head rotation (0.008–0.009) and jaw/mouth (0.004–0.007) carry the effect in every run; the eye region and the brows contribute nothing. Groups are not additive: zeroing head rotation alone costs as much as, or more than, zeroing the whole partner face. A static partner face (the conversation mean) costs only 0.002–0.003, while misaligned movement (time-shuffled, or another conversation's face) costs as much as removal: the model is sensitive to movement that is aligned with the audio.相手の顔係数を 1 グループずつゼロにしたとき(自分の顔は残す)の主指標の AUC の低下.3 回の学習.頭の回転(0.008〜0.009)と顎・口元(0.004〜0.007)が毎回効いており,目元と眉は寄与しない.グループは加法的でなく,頭の回転だけをゼロにしても相手の顔全体を消したのと同じかそれ以上に下がる.相手の顔を静止(会話平均)させても 0.002〜0.003 しか下がらないが,音声とずれた動き(時間シャッフル,別の会話の顔)は消したときと同じだけ下がる.モデルは音声と同期した動きに敏感である.
The objective matters目的関数が必要
Without the turn-yield objective, probes on the hidden state find no facial turn-taking information (logistic probe: −0.006 [−.011, −.002] with the real faces). The model receives the face and predicts it, but next-token training alone does not turn it into turn-taking information.ターン予測の目的関数なしでは,隠れ状態へのプローブで顔由来のターンテイキング情報は見つからない(ロジスティックプローブ: 実際の顔で −0.006 [−.011, −.002]).モデルは顔を受け取り,顔を予測もするが,next-token の学習だけではターンテイキングの情報にならない.
Why the label must not come from the videoラベルを映像から作ってはいけない理由
As a control, we repeat the intervention with a label derived from the mask of valid facial coefficients. On continuous recordings this mask marks face tracking, and the label is unrelated to speech-based turn ends. The intervention nevertheless gives ΔAUC 0.097 [.078, .116], five times the largest effect above, and the usual controls do not expose it. Replacing one stream at a time attributes 0.092 to the model's own recorded face and 0.005 to the partner's face, and on speech-derived turn ends the same head scores AUC 0.46.対照実験として,有効な顔係数のマスクから作ったラベルで同じ介入を行った.連続収録ではこのマスクは「顔が追跡できているか」を表し,発話に基づくターン終了とは無関係である.それでも介入の効果は ΔAUC 0.097 [.078, .116] と,上の最大の効果の 5 倍になり,通常の対照実験では見抜けない.ストリームを 1 本ずつ差し替えると,0.092 がモデル自身の録画の顔,0.005 が相手の顔に帰属し,発話由来のターン終了では同じヘッドの AUC は 0.46 になる.
More input → output examples入力 → 出力の例
User (recorded): “The frog said, okay, well then we can go on a diet together. We’ll eat half of this.” Model (generated): “What kind of food are you eating right now? Oh, that’s so good. I’m like trying to get salty.”
User (recorded): “I just think it’s wrong to bring dogs because half of them end up passing by.” Model (generated): “I understand. I agree, or my dog being there that’s easy. Okay, so here’s what we do here. I have a lot of animal knowledge and some dogs …”
Qualitative illustrations only; no numbers are derived from these clips. The three clips on this page were selected from 30 held-out turn shifts on which the model started to speak within two seconds: they are the ones whose replies fit what the user said. The model was fine-tuned on about 160 hours, and in most of the other clips the reply is fluent and well timed but off topic, or only a short acknowledgement. The clips illustrate the input and output modalities and the timing of the response. User lines are automatic transcripts of the recording; model lines are the text stream the model generated, which matches its speech.定性的な例であり,これらの動画から数値は出していない.このページの 3 本は,未使用会話の話者交替のうちモデルが 2 秒以内に話し始めた 30 場面から,応答がユーザの発話とかみ合っているものを選んだ.モデルは約 160 時間の微調整であり,それ以外の多くの場面では,応答は流暢でタイミングも妥当だが,話題が合っていないか,短い相づちにとどまる.これらの動画が示しているのは,入出力の形式と応答のタイミングである.User の行は録音の自動書き起こし,Model の行はモデルが生成したテキスト(音声と一致している).
Limitations限界
The effect is small in absolute terms, as is the facial contribution that dedicated turn-taking predictors report on the same corpus; it is consistent across three training runs and on the 64 held-out conversations whose speakers never appear in training, and it doubles at 0 dB SNR in every run. With 8.5 times more training data (one seed) both models predict shifts much better (AUC .779 / .780); the dependence on the partner's face persists but shrinks (0.003), and the own-face gain disappears. The 61 coefficients carry gaze only coarsely and no gestures or posture; the head is evaluated offline and teacher-forced. The generation test is exploratory (1,200 prompts per run, three runs): without the partner's face the model starts speaking before a hold in 50.4% of cases against 41.4% (+9.0 points [6.5, 11.4]), and the gap between its take rates before shifts and before holds narrows by 0.042 [.009, .076] pooled, in two of the three runs.効果の絶対値は小さく,同じコーパスでターンテイキング専用の予測器が報告している顔の寄与と同程度である.ただし 3 回の学習で一貫し,話者が学習に出てこない 64 会話でも同じで,0 dB の雑音下では全学習で 2 倍になる.学習データを 8.5 倍にすると(1 seed),両モデルとも話者交替の予測は大きく良くなり(AUC .779 / .780),相手の顔への依存は残るが縮み(0.003),自分の顔による上積みは消える.61 係数は視線を粗くしか運ばず,ジェスチャーや姿勢は含まない.ヘッドの評価はオフラインで teacher-forced.生成テストは探索的(各 1,200 プロンプト × 3 回): 相手の顔が無いと,相手が続ける間の前で話し始める率が 41.4% から 50.4% に増え(+9.0 ポイント [6.5, 11.4]),交替前と継続前の話し始め率の差は 0.042 [.009, .076] 縮む(プール,3 回中 2 回).